Savings Engine
The Savings Engine turns endpoint software usage into ranked cost-reduction recommendations. Where Optimization reports what is reclaimable per data source, the Savings Engine scores the whole installed estate and orders the results by confidence-weighted annual savings — so the recommendations you act on first are the ones with both the largest saving and the strongest evidence behind them.
Run Optimization
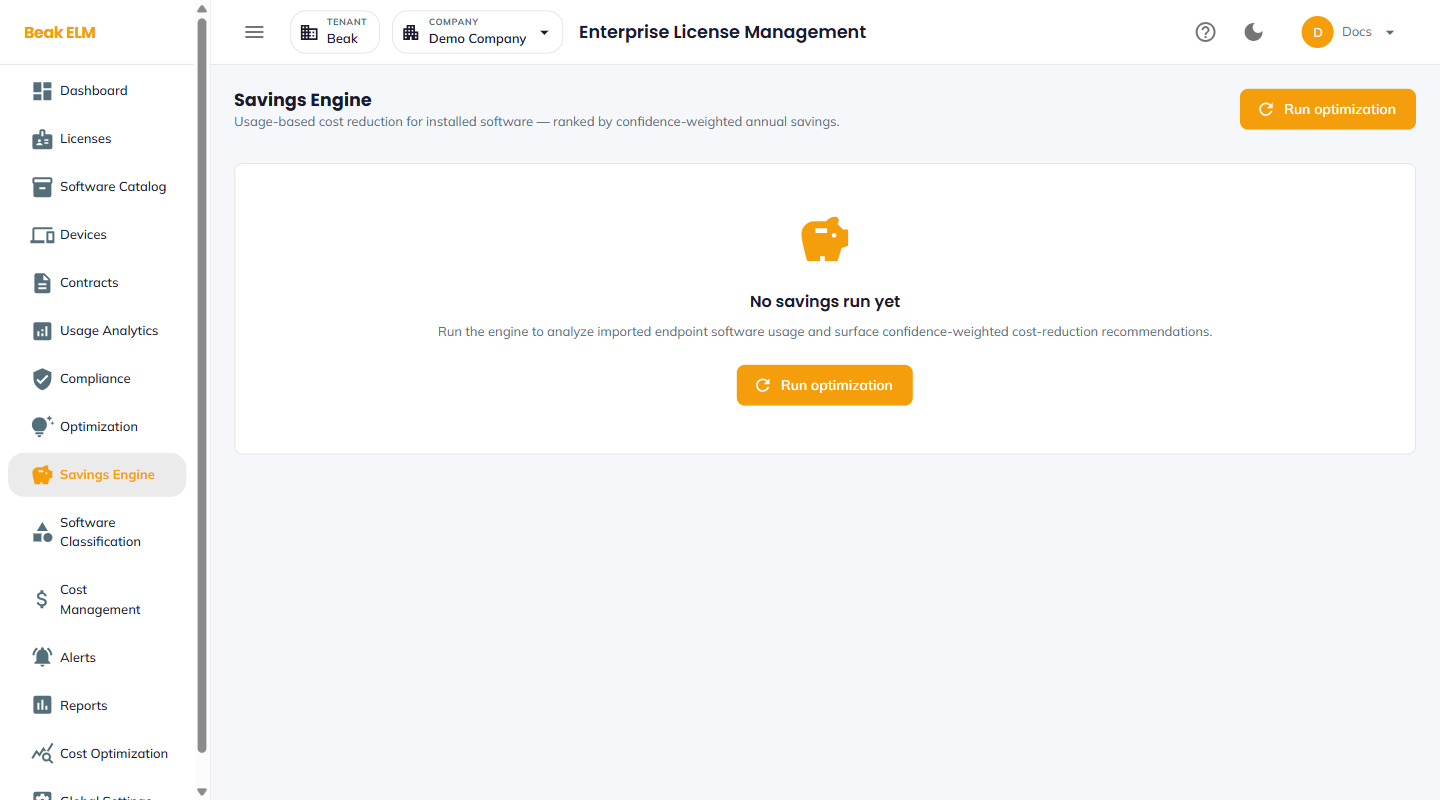
The engine does not run continuously — it produces a point-in-time result set. Run optimization, available both in the page header and in the empty state, analyses the imported endpoint software usage and surfaces the recommendations. Until the first run completes the page shows No savings run yet.
Re-run the engine after an endpoint inventory import, a connector sync, or a change to Optimization Thresholds — the results reflect the data and thresholds present at the moment of the run.
What the Engine Reads
Recommendations are derived from the install-level usage data described on Endpoint Inventory — installs, devices, unique users, and the last-used recency buckets. A company with no imported endpoint inventory has nothing to model, and the engine returns an empty result set.
Note: Confidence weighting is why the ranking is not a straight sort by dollar value. An install with sparse usage telemetry yields a lower-confidence saving and is ranked below a smaller but well-evidenced one.
Best Practices
- Import or sync endpoint inventory before the first run — see Endpoint Inventory. The engine has no other data source.
- Re-run the engine on the same cadence as your inventory refresh so the ranking reflects current usage rather than the state at the last run.
- Work the ranked list top-down. The confidence weighting already accounts for evidence quality, so skipping ahead to a larger raw saving usually means acting on weaker data.
- Treat
Savings Engineoutput as the candidate list and Optimization as the per-source tracking surface — the two answer different questions.
Related Pages
- Optimization — Per-source reclaim and right-sizing recommendations
- Endpoint Inventory — The install and usage data the engine reads
- Cost Optimization — Statistical spend models over connector data
- Optimization Thresholds — Thresholds applied on each run